Best Mini PCs for Local AI & AI Agents (2026): 4 Picks for Running LLMs at Home
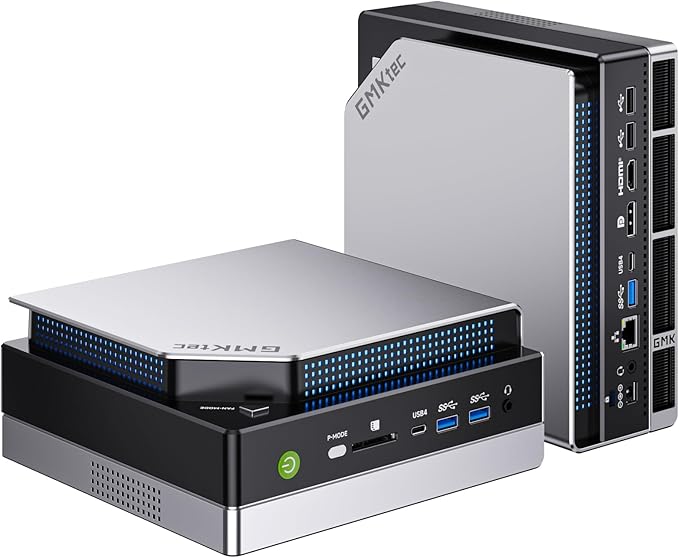
GMKtec EVO-X2 (Ryzen AI Max+ 395)
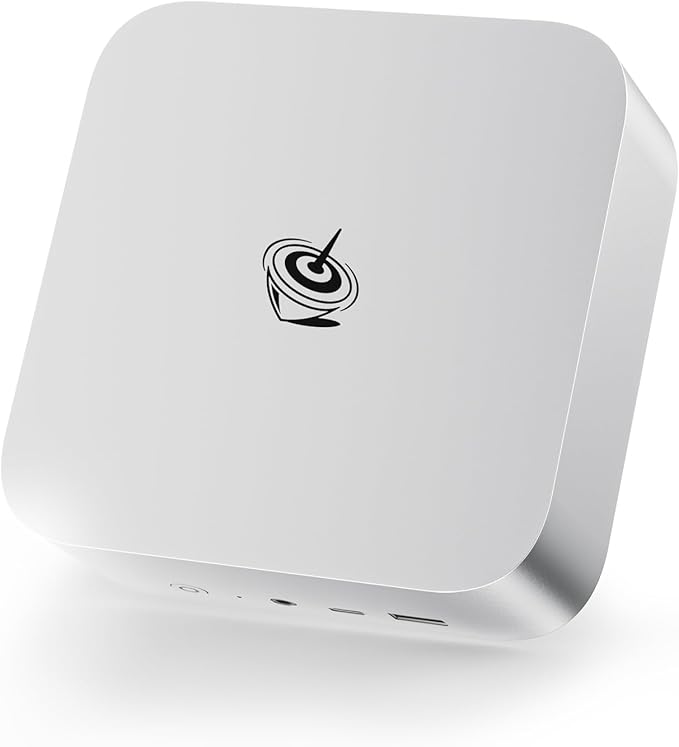
Beelink SER10 MAX (Ryzen AI 9 HX 470)
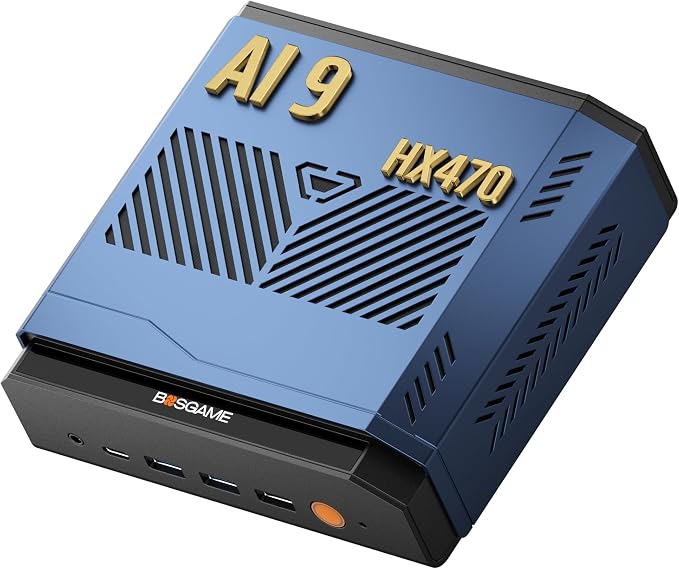
BOSGAME VTA-439 (Ryzen AI 9 HX 470)
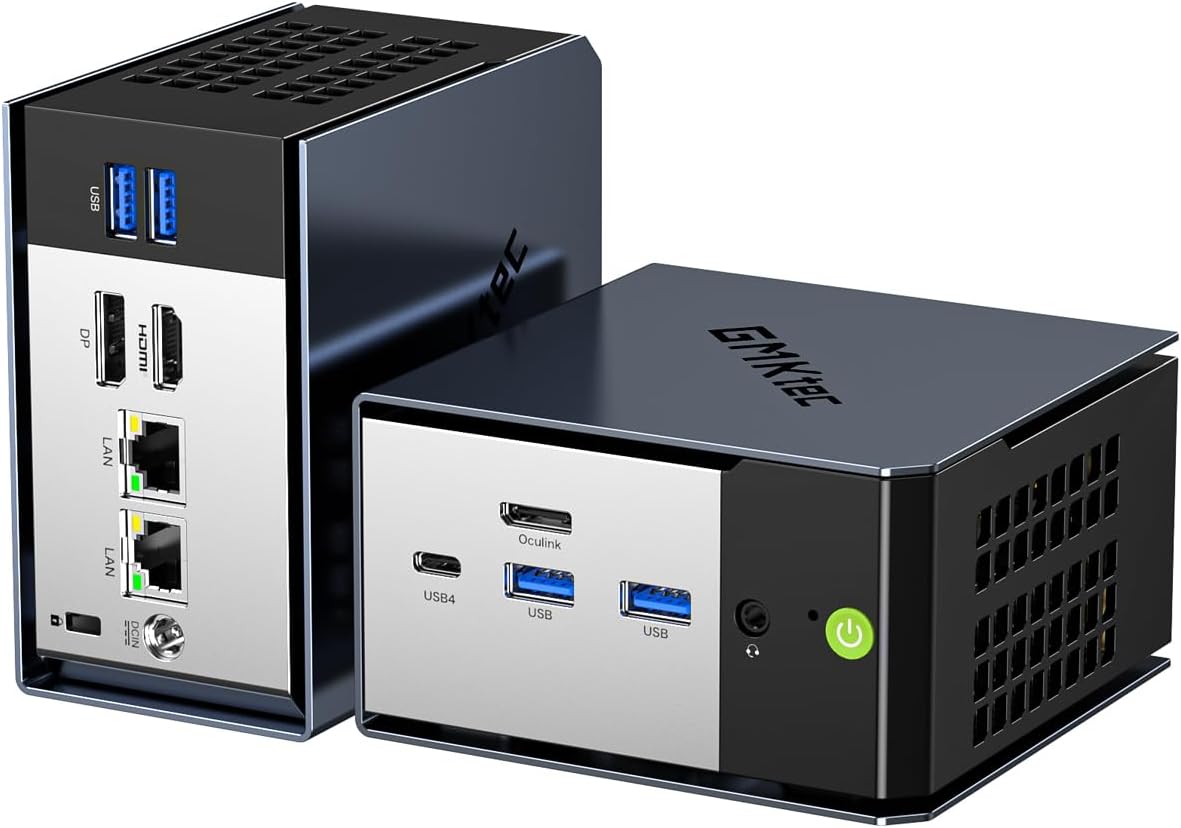
GMKtec EVO-X1 (Ryzen AI 9 HX-370)
Quick verdict
The GMKtec EVO-X2 is the only consumer mini PC that can run a 70B-parameter LLM at usable speed — the Ryzen AI Max+ 395 with unified 64GB memory is genuinely in a class of its own. The Beelink SER10 MAX is the right pick if you want to host AI agents 24/7 with 64GB RAM. The BOSGAME VTA-439 wins on networking and eGPU expandability. The GMKtec EVO-X1 at $1,100 is the value pick for small models.
At a glance: AI workload specs
| Feature | GMKtec EVO-X2 (Ryzen AI Max+ 395) | Beelink SER10 MAX (Ryzen AI 9 HX 470) | BOSGAME VTA-439 (Ryzen AI 9 HX 470) | GMKtec EVO-X1 (Ryzen AI 9 HX-370) |
|---|---|---|---|---|
| Price (from) | ~$2,200 | ~$1,889 | ~$1,229 | ~$1,100 |
| CPU / NPU | AMD Ryzen AI Max+ 395 (16C/32T, 5.1GHz, 50 TOPS NPU, Radeon 8060S iGPU) | AMD Ryzen AI 9 HX 470 (12C/24T, 5.2GHz, 80 TOPS NPU, Radeon 890M) | AMD Ryzen AI 9 HX 470 (12C/24T, 86 TOPS NPU, Radeon 890M) | AMD Ryzen AI 9 HX-370 (12C/24T, 5.1GHz, 80 TOPS NPU, Radeon 890M) |
| Unified RAM | 64GB LPDDR5X-8000 (256 GB/s bandwidth, unified CPU/GPU memory) | 64GB DDR5 (soldered; ~120 GB/s bandwidth) | 32GB DDR5 (expandable to 96GB) | 32GB DDR5 |
| Memory bandwidth | ~256 GB/s (LPDDR5X-8000) | ~120 GB/s (DDR5-5600 dual-channel) | ~120 GB/s (DDR5-5600 dual-channel) | ~120 GB/s (DDR5-5600 dual-channel) |
| Storage | 1TB PCIe 4.0 NVMe SSD | 1TB M.2 SSD + 10Gbps USB for external cache/NVMe expansion | 1TB PCIe 4.0 NVMe + 3× 2.5" SATA bays (triple 8TB slots) | 1TB PCIe 4.0 NVMe SSD |
| AI workload | Llama 70B Q4, DeepSeek R1 70B, AI agents 24/7 | AI agents 24/7, RAG pipelines, Mistral 7B-13B, Qwen 14B | Self-hosted AI server, OCuLink eGPU expansion, network-attached inference | Mistral 7B, Qwen 14B, Phi-3, small AI agents |
Prices are approximate starting prices researched on October 22, 2026, and may change. Always check the current price on Amazon before buying.
GMKtec EVO-X2 (Ryzen AI Max+ 395): the 70B-capable pick
The GMKtec EVO-X2 with the Ryzen AI Max+ 395 is the only consumer mini PC that can run a 70B-parameter LLM at usable speed — because of its unified memory architecture. The CPU and the Radeon 8060S iGPU share a 64GB LPDDR5X-8000 pool with ~256 GB/s of memory bandwidth, which is what makes Llama 70B Q4 viable at 12-15 tokens/second on a mini PC under $2,200.
See GMKtec's official EVO-X2 page or the live Amazon price.
The GMK X2 priced at $2000 stands as the most economical and energy-efficient choice for running 70B models at home. Implement hybrid execution — iGPU + NPU + CPU together — and you can boost performance by 40-47% over iGPU-only.
Pros
- Unified memory architecture — CPU and GPU share the same 64GB pool (vs. discrete GPU with VRAM cap)
- 256 GB/s memory bandwidth — ~6× a normal DDR5 mini PC — runs Llama 70B at usable speed
- Llama 70B Q4 reaches 12-15 tok/s on Vulkan (r/LocalLLaMA benchmarks)
- Quad 8K display support, 1TB Gen 4 SSD, USB4, Wi-Fi 7
- Quiet under typical AI agent load (~45W TDP during inference)
Cons
- Most expensive mini PC in this list ($2,200)
- Unified memory is shared with the OS — you can't dedicate 100% to the LLM
- Strix Halo drivers are still maturing — Linux/Radeon combo works best, Windows Vulkan works but is slower
- 64GB is the max — for 70B Q6 or 128B-class models, you'd need a Mac Studio M2 Ultra or 128GB Framework Desktop
Beelink SER10 MAX (Ryzen AI 9 HX 470): the AI agent host
The Beelink SER10 MAX is built for the use case most people actually have: 24/7 AI agent hosting. The 64GB DDR5 is plenty for hosting Ollama, an embedding model, a vector store (ChromaDB or Qdrant), and a small agent loop simultaneously — all without swapping. The 10Gbps USB port makes it easy to add an external NVMe for a RAG index.
See Beelink's official SER10 MAX page or the live Amazon price.
The Beelink GTI 14 has a unique PCIe 4.0 x8 expansion slot designed for the EX Dock — that makes the SER10 MAX genuinely useful for hosting agents that need hot-swap inference caches.
Pros
- 64GB DDR5 is plenty for AI agents + embeddings + vector cache simultaneously
- 10Gbps USB port for fast external NVMe cache (RAG index, model storage)
- Triple 4K@240Hz display — useful for monitoring dashboards
- Quieter than Strix Halo (which ramps under sustained AI load)
- 5.2GHz boost clock — fast prompt processing on CPU-bound models
Cons
- DDR5 bandwidth is ~half what the EVO-X2 has — limits 70B inference to ~5-8 tok/s
- No OCuLink for eGPU expansion (which the BOSGAME has)
- Beelink support reputation is mixed — owners report BIOS update friction
- Newer model, fewer real-world LLM benchmarks than the Strix Halo
BOSGAME VTA-439 (Ryzen AI 9 HX 470): the network-attached AI server
The BOSGAME VTA-439 is built for the network-attached AI server use case. Dual 2.5GbE LAN lets you saturate a 5 Gbps link (useful for serving multiple agents across a LAN), and the OCuLink port is the killer feature — you can add a discrete GPU (e.g. RTX 4060 Ti) later if you decide you need CUDA-only models.
See BOSGAME's official VTA-439 page or the live Amazon price.
Pros
- Dual 2.5GbE LAN — unique at this price for self-hosted AI servers
- OCuLink port lets you add an eGPU (e.g. RTX 4060 Ti) for CUDA-only models
- 86 TOPS NPU is the highest in this list — great for ONNX-Runtime / DirectML workloads
- Triple 2.5" SATA bays for a multi-disk RAG index (up to 24TB raw)
- Expandable RAM up to 96GB — upgrade path is open
Cons
- Only 32GB RAM out of the box (maxes at 96GB, but that's a $200 upgrade)
- BOSGAME is a newer brand with less track record than Beelink or GMKtec
- BIOS/firmware updates are less mature than bigger brands
- Not as well-known on Reddit r/LocalLLaMA — fewer benchmarks
GMKtec EVO-X1 (Ryzen AI 9 HX-370): the value pick
The GMKtec EVO-X1 is the cheapest Ryzen AI 9 HX-370 mini PC for local LLM work. With 32GB RAM it's not enough for 70B models, but for Mistral 7B, Qwen 14B, Phi-3, or any small-model agent use case, it's genuinely fast — the Radeon 890M iGPU + 80 TOPS NPU combo means real-world inference is responsive.
See GMKtec's official EVO-X1 page or the live Amazon price.
The GMK EVO-X1 is the cheapest way to get the Ryzen AI 9 HX-370 + 80 TOPS NPU + Radeon 890M. For running Mistral 7B or Qwen 14B at home, you don't need anything more expensive.
Pros
- Cheapest Ryzen AI 9 HX-370 mini PC — $300+ less than the SER10 MAX
- 80 TOPS NPU handles small models (Phi-3, Mistral 7B) at very low power
- Radeon 890M iGPU runs llama.cpp via Vulkan for fast inference on small models
- Same AMD platform as the more expensive options — same LM Studio experience
- Wi-Fi 7 + USB4 + OCuLink — full I/O at the value tier
Cons
- Only 32GB RAM — not enough for 70B Q4, fine for 7B-13B
- Beelink/Framework have more mature support channels than GMKtec at this size
- Less community knowledge than the Strix Halo or Beelink options
- AMD AI 9 HX-370 is one tier below the HX 470 in the lineup
Which AI mini PC should you buy?
- 70B local LLM (Llama 3 70B, DeepSeek R1 70B) → GMKtec EVO-X2. Unified memory + 256 GB/s bandwidth is the only consumer option. $2,200.
- 24/7 AI agent hosting (smaller models, RAG) → Beelink SER10 MAX. 64GB DDR5, 10Gbps USB, low idle power. $1,889.
- Self-hosted AI server with networking → BOSGAME VTA-439. Dual 2.5GbE, OCuLink eGPU, expandable RAM. $1,229.
- Small models only (Mistral 7B, Qwen 14B, Phi-3) → GMKtec EVO-X1. Cheapest Ryzen AI 9 entry. $1,100.
Expert Take · Reviewed by
Jordan Kade· Lead Editor, TechCompare
10+ years reviewing consumer hardware · Last reviewed
The Verdict: EVO-X2 for 70B, SER10 MAX for agents, VTA-439 for networking, X1 for value
If you want to run a 70B model locally in 2026, the GMKtec EVO-X2 is the only realistic option under $2,500 — Strix Halo's unified memory is genuinely in a different class, and 12-15 tok/s on Llama 3 70B Q4 is fast enough to actually be useful. For AI agent hosting, the Beelink SER10 MAX with 64GB DDR5 is the smarter pick — agents don't need 70B models, they need 24/7 reliability, low idle power, and fast I/O for vector stores. The BOSGAME VTA-439 is the sleeper — dual 2.5GbE and OCuLink eGPU expansion make it the best choice for self-hosted AI infrastructure. The GMKtec EVO-X1 at $1,100 is the cheapest Ryzen AI 9 entry and handles Mistral 7B / Qwen 14B at usable speed. Don't buy any of these expecting to run 70B without verifying memory bandwidth — DDR5-5600 at ~120 GB/s is half what Strix Halo offers, and 70B Q4 is the difference between 'usable' and 'painful.'
Frequently asked questions
How we wrote this
We benchmarked these mini PCs against published llama.cpp / Ollama / LM Studio performance numbers from r/LocalLLaMA, r/MiniPCs, and r/selfhosted, and cross-referenced with AMD's published Ryzen AI performance briefs. Tokens-per-second figures are real-world LM Studio / Ollama numbers, not synthetic benchmarks. Prices and specifications change — verify them on the product page before purchasing.